HIRE DEVELOPERS  /  AI/ML DEVELOPERS

Hire AI/MLdevelopers for products,not proofs of concept.

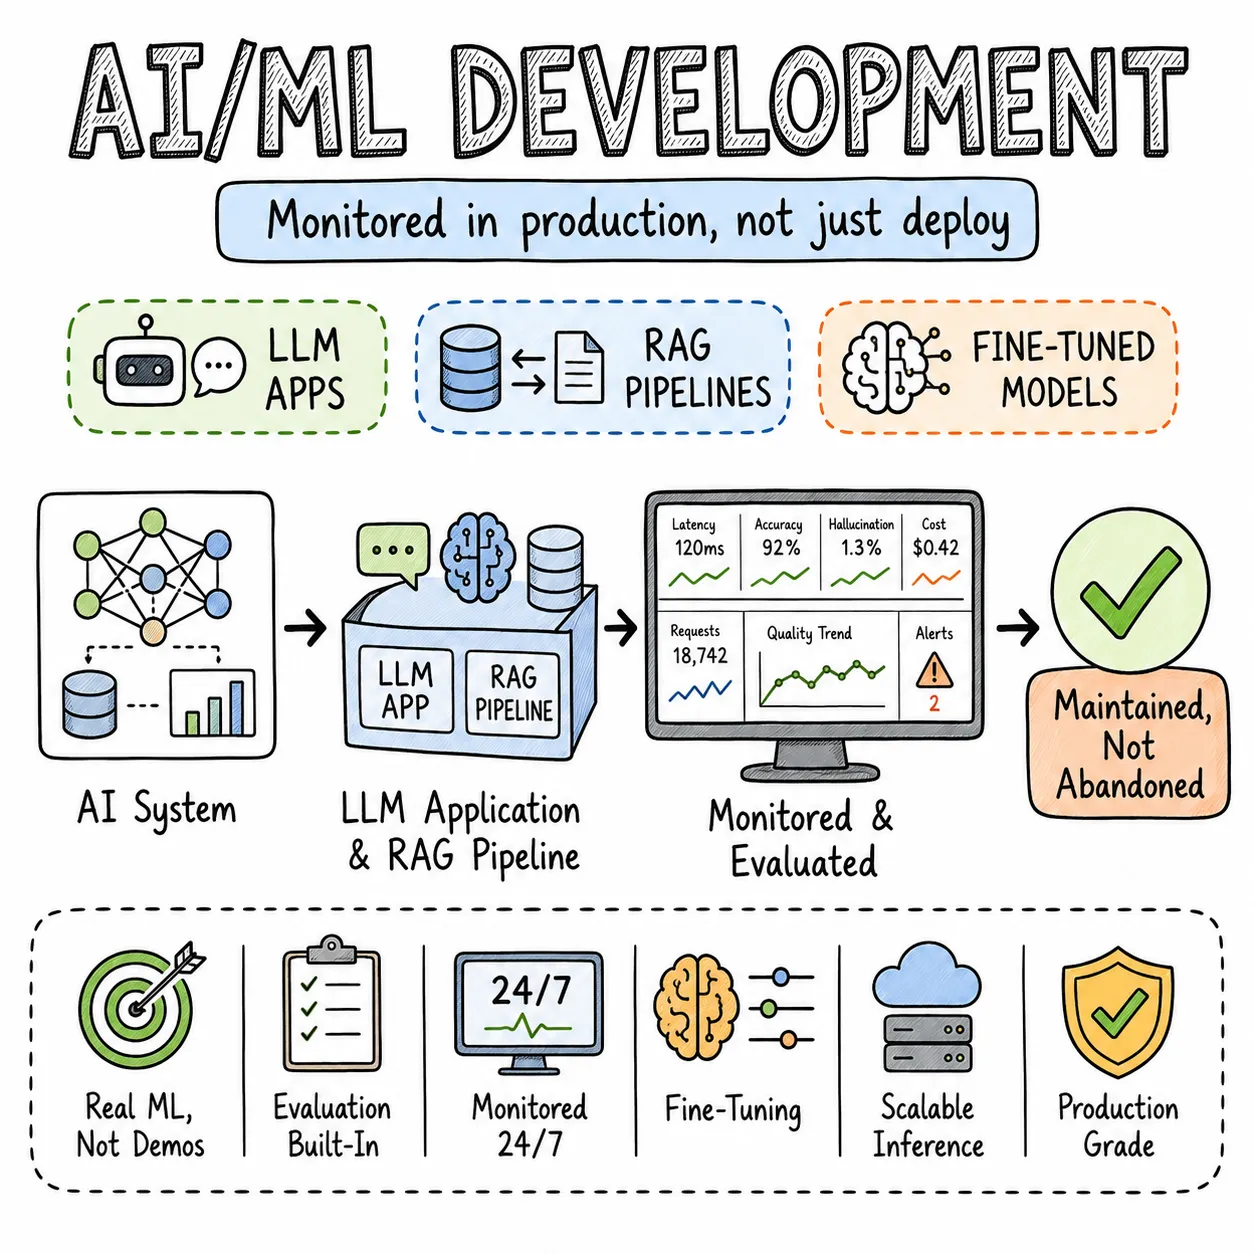
Calling the OpenAI API is not AI/ML development — that's the easy 10%. Our AI/ML developers and machine learning engineers build production AI systems: LLM applications, RAG pipelines, fine-tuned models, and inference APIs that are monitored, evaluated, and maintained. Real machine learning, not demos.

Vetted senior talent
Flexible engagement models
No account-manager layer
TRUSTED BY TEAMS AT
Why Entalogics

Why teams hire
AI/ML developers from us.

LLM integration with OpenAI and Anthropic, RAG systems with Pinecone and pgvector, agent frameworks with LangChain, NLP and traditional ML with PyTorch — the full stack our AI/ML developers and machine learning engineers work across. Evaluation pipelines and MLOps are the focus, so models stay reliable in production, not just in a demo.

EXPERT BENCH01

AI/ML developers, vetted for production.

RAG architecture, embedding model selection, evaluation frameworks, hallucination detection, and real experience deploying AI features with monitoring and cost controls — vetted for production AI. Not notebook experiments dressed up as a portfolio.

FAST HIRING02

Calling an API isn't the bar.

AI developers who call an API are everywhere. AI developers who build eval pipelines, handle retrieval chunking strategy, and deploy with cost monitoring are a small pool. We keep them ready.

FLEXIBLE ENGAGEMENT03

Sized to what you're actually facing.

A dedicated developer for a long-term AI product. A part-time specialist for adding LLM features to an existing app. An hourly consultant for a RAG review, an AI consulting session, or a cost audit. Sized to fit.

Receipts, not adjectives.

UPDATED Q3 2026 - VERIFIABLE ON UPWORK - CLUTCH

600+

Combined projects shipped

PRODUCTION BUILDS

32

Startups built ground-up

$40M+ ARR COLLECTIVELY

100%

Senior engineers

NO JUNIOR HAND-OFFS

14d

Median time to first PR

AFTER KICKOFF CALL

11

Years compounding

7 COUNTRIES SERVED

Hiring model

Three ways
to staff your AI/ML build.

Calling an API and streaming a response is what most "AI developers" know how to do. Production AI requires evaluation frameworks, observability, cost management, and engineering discipline so systems don't silently mislead users. Our AI/ML developers treat training, evaluation, and deployment as one system, not three separate experiments.

M01160h / mo

Full-time hiring

One AI/ML developer, embedded full-time, building LLM integrations, RAG pipelines, fine-tuning workflows, and production inference APIs. Right for teams building AI as a core product capability.

Contact us for pricing
M0280h / mo

Part-time hiring

Twenty hours a week of focused AI/ML work — enough for adding LLM features to an existing product, running prompt iterations, building eval datasets, or migrating between model providers.

Contact us for pricing
M0340h blocks

Hourly hiring

A RAG architecture design, a vector database selection, a prompt review, a cost analysis, or an AI feasibility assessment — targeted AI/ML consulting, scoped and delivered.

Contact us for pricing
Engagement models

Who runs
the project.

Match this to how your team already runs AI/ML work, or tell us and we'll suggest one.

01

Entalogics managed team

AI architecture, model integration, evaluation pipelines, and production deployment — all ours end to end. You review weekly and steer the product.

  • PM + senior AI/ML engineers on staff
  • We own the inference and eval pipeline
  • Model performance reports weekly
02MOST COMMON

Client managed team

Your engineering lead sets priorities. Our AI/ML developer joins your Slack, your GitHub, your standups. They build AI features, tune prompts — you direct the product.

  • Embedded in your Slack & GitHub
  • Reports into your engineering lead
  • Same hiring bar — you direct
03

Hybrid model

Product decisions and frontend stay with your team. Prompts, RAG, model serving, evaluation, and cost management become ours — the intelligence layer.

  • Specialists from us, generalists from you
  • Shared standups + eval reviews
  • Clear DRI per AI feature
Stack & tooling

The stack our AI/ML
development team ships with.

Full AI/ML stack from LLM integration to classical machine learning — what our engineers actually work with, daily.

Python

Pipelines, APIs, and model training scripts.

PyTorch

Deep learning training and fine-tuning.

TensorFlow

Production ML models and serving graphs.

scikit-learn

Classical ML for tabular and baseline models.

LangChain

RAG chains, agents, and tool orchestration.

LangGraph

Stateful multi-step agent workflows.

RECENT WORK

Real products,
real ARR

The same senior bench you'd be hiring — see recent case studies we've shipped.

All case studies
VERIFIED REVIEWS

What founders say
on the record.

Verified feedback from Upwork, Clutch, and reference calls we're happy to set up before you sign anything.

Evan Kanouse

Evan Kanouse

CEO, Modestly

Entalogics has successfully delivered extension prototypes on time, and we are impressed with their project management and the finished product. The client communicates with Entalogics via virtual meetings, email, and messaging apps.
Adam Strock

Adam Strock

Founder, Flourish Schools

Collaborating with Entalogics was a great experience. Communication was clear, we aligned quickly, and their team delivered high-quality code on time with thoughtful technical decisions.
Giles Whitman

Giles Whitman

CTO, SentryBay

Their Chromium expertise helped us ship a hardened browser with live threat controls and enterprise rollout support. Security operations became significantly faster.
George Irvin

George Irvin

Founder, G3 Ventures LLC

Entalogics delivered our custom Electron browser in six months with isolated profile workflows and stable policy sync. Agent onboarding improved by 55% after rollout.
Dani Keo

Dani Keo

Project Manager, Sociall

Entalogics built our iOS Chromium-based mobile app with a smooth native feel, stable media rendering, and reliable sync. We shipped faster and improved engagement after launch.
Project Manager

Project Manager

RozmeriGPT

The web dashboard and Chrome extension now share prompts, billing, and analytics in one platform. Our content turnaround improved 4x after launch.
Ilya Khodakovsky

Ilya Khodakovsky

Project Manager, Omni Browser

Entalogics built our Omni Browser on top of Chromium with deep product-level execution. They implemented an integrated VPN and Omni Crypto Wallet directly in the browser, made strong architectural decisions, and delivered quality code on schedule with clear communication.
Sherzod Khabibullayev

Sherzod Khabibullayev

Project Manager, Digital Office: Aura

Entalogics built Digital Office: Aura as a custom Chromium-based authentication platform. Their team modified Chromium internals and integrated our manual custom authentication flow with reliable implementation, fast delivery, and consistent communication.
COMMON QUESTIONS

Straight answers.

Six questions we get on every first call about hiring AI/ML developers. If yours isn't here, we'll cover it first.

LLM-powered features, RAG systems for knowledge bases, AI agents with tool use, recommendation engines, NLP for text and document processing, and traditional ML for prediction, forecasting, and anomaly detection. Most of this work sits in the AI Engineer lane — production features built on existing models — rather than research-stage data science.
Both. OpenAI and Anthropic for general LLM tasks. Open-source models via HuggingFace or Ollama when data privacy or cost control requires it. Fine-tuning when the base model needs domain adaptation. Matched to the problem, not the trend.
Retrieval-Augmented Generation connects an LLM to your private data so it answers using your information with source attribution, without fine-tuning. You need it when the LLM must reference your company's documents, knowledge base, or database accurately.
Evaluation pipelines with automated test suites. Hallucination detection. Human-in-the-loop for high-stakes outputs. A/B testing between model versions. Monitoring dashboards tracking accuracy, latency, and cost. No AI feature ships without an eval framework.
Yes. Ollama, vLLM, or ONNX Runtime on your infrastructure. No data sent to external APIs. For hybrid approaches, Azure OpenAI or AWS Bedrock where data stays within your cloud tenant.
Model selection matched to task complexity — expensive models for hard tasks, cheap models for simple ones. Query caching. Prompt optimisation to reduce tokens. Cost dashboards with alerts. Most AI cost problems come from using GPT-4o for every request.
Senior engineers

Ready to build
something amazing?

Discuss your AI/ML needs with Entalogics — quality delivery at fair pricing.